Key takeaways
- Define the event that starts each service clock.
- Make calendars, pause reasons, and delegation explicit.
- Measure meaningful responses, not just notifications sent.
Putting this workflow into practice? Explore Automation Systems Architecture for implementation scope, controls, and next steps.
Automated reminders can make a business noisier without making it faster. A task assigned on Saturday may trigger an overdue warning before the responsible team returns on Monday. An invoice waiting for customer evidence may generate the same escalation as an ignored internal approval.
Business-hours escalation design makes the clock match the operating process. It defines when work becomes actionable, which calendar applies, what pauses the timer, and who receives the next escalation. The result should be clearer ownership, not a larger volume of notifications.
Define the promise before starting the clock
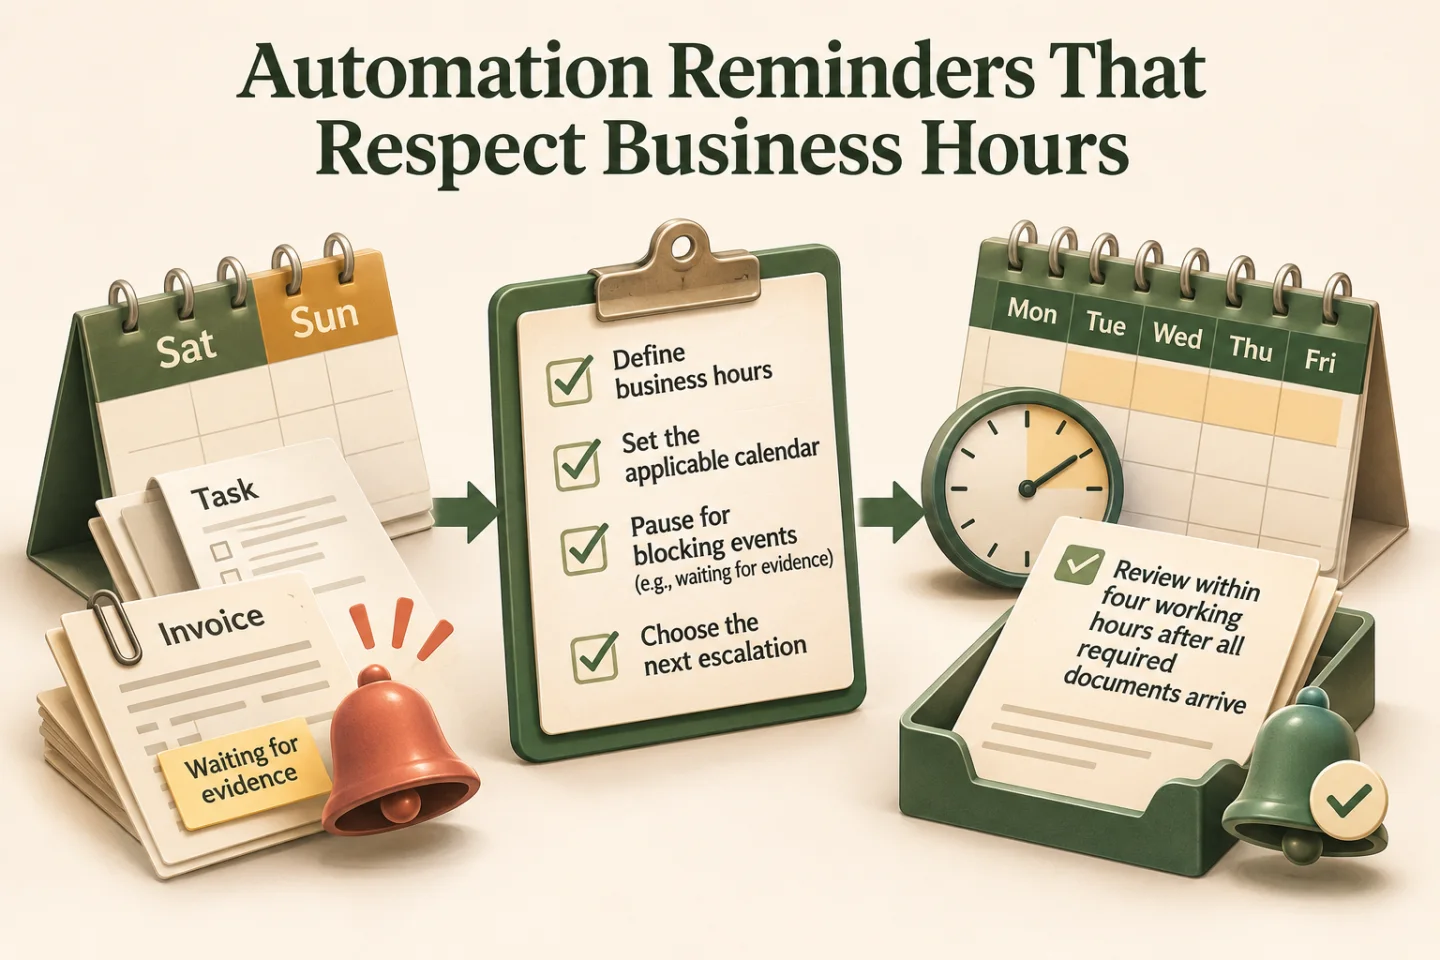
Write the service expectation in plain language. "Review within four working hours after all required documents arrive" is more precise than "resolve quickly." It also separates response time from final resolution, which may depend on an external party.
Identify the event that starts the clock. A form submission, validated brief, assigned owner, and complete evidence packet are different starting points. Choose the one that matches the promise made to the customer or internal team.
Keep the original receipt time even when the actionable clock begins later. Otherwise the business may hide intake delays by starting measurement only after somebody eventually assigns the task. Report both intake-to-ready time and ready-to-response time where they matter.
Model calendars explicitly
Store the responsible team's timezone, working days, working hours, and holiday calendar. Do not infer operating hours from the server's timezone. A system hosted overseas can still support an India-based accounts team without shifting every reminder.
| Calendar element | Decision to document |
|---|---|
| Timezone | Which team's local time controls the promise? |
| Working window | Are lunch breaks or shifts relevant? |
| Holidays | Who maintains and approves the calendar? |
| Cross-team handoff | Does the next stage use another calendar? |
| Urgent exceptions | Which cases follow a separate on-call route? |
| Pause policy | Which waiting states stop the clock? |
Use a maintained date-time library rather than hand-written arithmetic for timezones and calendar boundaries. Test daylight-saving transitions for teams in regions that use them, even if your own team does not.
- Define the response promise
- Apply the working calendar
- Expose pauses and escalation
- Assign the next action
A visual map of this article’s approach. The detailed requirements and exceptions are explained in the surrounding sections.
Make pauses visible and controlled
Waiting for required customer evidence may justify pausing a particular service clock. Waiting because nobody accepted ownership usually should not. Define allowable pause reasons and who may apply them.
Record the pause start, reason, evidence request, and responsible person. Show paused work in the queue instead of removing it from view. A customer who never receives the evidence request should not become invisible behind an internal "waiting" status.
On resumption, continue from the agreed remaining time rather than resetting the entire allowance unless policy explicitly requires a reset. Repeated pauses and restarts should be reportable because they can reveal a broken intake process or misuse of the timer.
An illustrative Friday handoff
Suppose an internal review is ready at 4 p.m. Friday and the team works until 6 p.m., then resumes at 10 a.m. Monday. With a four-working-hour target, two hours remain after Friday's work window. The illustrative due time is noon Monday, assuming Monday is not a holiday.
Now suppose the reviewer requests missing evidence at 5 p.m. Friday and policy permits a pause. The system records one hour consumed, the request evidence, and the remaining three hours. It resumes only when the required material is received and validated under the process.
This is an operating example, not a recommended universal SLA. The right duration depends on capacity, customer expectations, and risk. The important part is that the team can reproduce the calculation and explain it.
Escalate to a useful next action
An escalation should tell the recipient what is blocked, how long it has waited under the relevant clock, what was already attempted, and what decision is needed. Avoid sending a manager a link with no context and expecting them to reconstruct the case.
Start with the assigned owner, then the defined backup or team lead. Do not copy the founder on every routine delay. Reserve higher escalation for the cases where that person can actually change the outcome.
Deduplicate notifications. A task that remains overdue should not generate a new email every minute. Record which escalation stage has been sent and send again only according to an approved reminder policy or a meaningful change in the case.
Separate delivery from acknowledgement
An email accepted by the mail provider is not proof that the owner read it. A message delivered to a chat channel is not proof that someone took responsibility. Record acknowledgement or ownership changes separately when the process depends on them.
Provide a backup notification route for important failures, but do not expose sensitive case details in broad channels. A short notification can link to an authenticated record containing the evidence and action controls.
If notification delivery fails, create an operational alert. Do not mark the business case as escalated successfully while the message is stuck in an email queue. The automation's own communication path needs monitoring too.
Track these separately. Evidence for one does not automatically confirm the others; use the article’s review and ownership checks.
Measure whether the reminders improve work
Track time to first meaningful response, time in each waiting state, overdue age, and repeated escalation reasons. Compare outcomes before and after changing the policy. More notifications are not evidence of better service.
Review cases that meet the response target but remain unresolved for a long time. A quick acknowledgement can make an SLA dashboard look healthy while the customer still waits. Use a separate resolution measure where the business can reasonably own that outcome.
Test weekends, holidays, owner absence, reassignment, changed calendars, paused work, and failed notifications. Recalculate due times deliberately when policy changes; avoid silently rewriting historical performance figures with a new calendar.
For broader context, read the lead-routing automation guide and lead response and ownership guide. Explore automation systems support and tell me where work currently waits without an owner. That is the right starting point for useful escalation.
Frequently asked questions
How should an escalation clock handle nights and holidays?
Document staffed hours, time zone, holidays and the event that starts the clock. Preserve the original event time and distinguish elapsed customer waiting from the business time counted by the agreed rule.
Should every overdue event alert the founder immediately?
Route alerts to the responsible owner and backup according to urgency and impact. Record acknowledgement and resolution so repeated reminders do not substitute for an accountable recovery action.
Further implementation guidance
For an implementation example of explicit retries and fallback paths, see the AWS workflow retry and error-handling documentation. Choose the recovery policy from the business operation and verify the outcome in your own stack.
Related implementation guides

Founder, The Night Marketer (Shopify Select Partner). The agency has served 450+ brands since 2015.
Automation Systems Architecture
For teams where leads, orders, operations, or reporting still depend on memory, WhatsApp nudges, and manual sheet updates.